AI Keeps Ranking Your Brand Behind Competitors? How to Tell If It's Unclear Value Props, Weak Evidence, or Poor Product Fit
Your brand makes the AI recommendation list but keeps appearing behind competitors. Learn how to separate poor product fit, unclear value props, and weak evidence, then choose the right action for each question
Track AI search visibilityNo install
Updated by
AI-assisted for research support
12 Min Read
Updated on Sep 28, 2026
TL;DR
- First, check multiple answers for the same sub-intent, platform, and region to see whether your brand repeatedly appears behind competitors. Then compare the reasons AI gives for each brand side by side. If competitors win on product requirements your brand genuinely does not meet, the issue is poor product fit. If AI describes your brand vaguely or focuses on the wrong point, your value props are unclear. If AI identifies your value prop but competitors have third-party reviews, comparisons, or certifications to support theirs, your evidence is weak.
- If the product is a poor fit, stop competing for that question. If the value prop is unclear, add the relevant product details, conditions, and limitations to the right page. If the evidence is weak, add external proof that matches the claim.
- Dageno's brand visibility ranking is based on a set of collected answers. To see which brand comes first in a single answer, open the Source answer and assess its structure manually.
- All three causes can occur at once. Check product fit first, then on-site information, and finally external evidence. This keeps you from assigning content work for capabilities the product does not have.
1. First Check Whether Appearing Behind Competitors Is a Pattern, Not Just One Answer
1.1 If an Answer Groups Brands by System or Use Case, the Order Between Groups Is Not a Ranking
In this article, "appearing behind" means that your brand and a competitor appear in the same answer and the same candidate group, with a clear order in a list, table, or continuous passage. The evidence comes from the original answer, not from a newly calculated position metric.
Some answers first group products by mobile operating system, price tier, or use case. On page 7 of 108 under the Choose by budget or tier sub-intent, Germany's Google AI Mode answer begins:
“Die besten Allround-Smartwatches unter 300 Euro sind die Google Pixel Watch 3 (für Android-Nutzer) und die Apple Watch SE 3 (für iPhone-Nutzer) … Da das Betriebssystem Ihres Smartphones die Wahl stark einschränkt, teilen sich die Top-Empfehlungen in verschiedene Kategorien auf” (The best all-round smartwatches under EUR 300 are the Google Pixel Watch 3 for Android users and the Apple Watch SE 3 for iPhone users. Because your smartphone's operating system greatly limits the choice, the top recommendations are divided into different categories.)
The answer then covers "Für Android-Nutzer" before "Für iPhone-Nutzer." The two brands serve different mobile systems, so the Android group appearing before the iPhone group should not be recorded as Pixel ranking first and Apple second. For an answer like this, record "grouped by system," then read the selection reasons within each group separately.
If the brand does not appear among the candidates at all in comparable answers, use the diagnostic method for a product that fits but is not recommended. This article only addresses cases where the brand already appears in a position that can be compared with competitors.
1.2 Brand Visibility Ranking and the Order in One Answer Are Different Data
In Dageno, go to Market overview -> Competitive landscape -> AI visibility leaderboard. Apple ranks #1 in the Smart Watches market, with 62.31% visibility. This result aggregates collected answers across the whole market.
Now go to Demand & insights -> Search intents -> Recommendations -> Choose by budget or tier. Apple's Visibility rank is #4, its visibility is 47.22%, and the Leading brands are Amazfit, Xiaomi, and Samsung. This view covers only the budget or price-tier sub-intent, so its scope is narrower than the whole market.
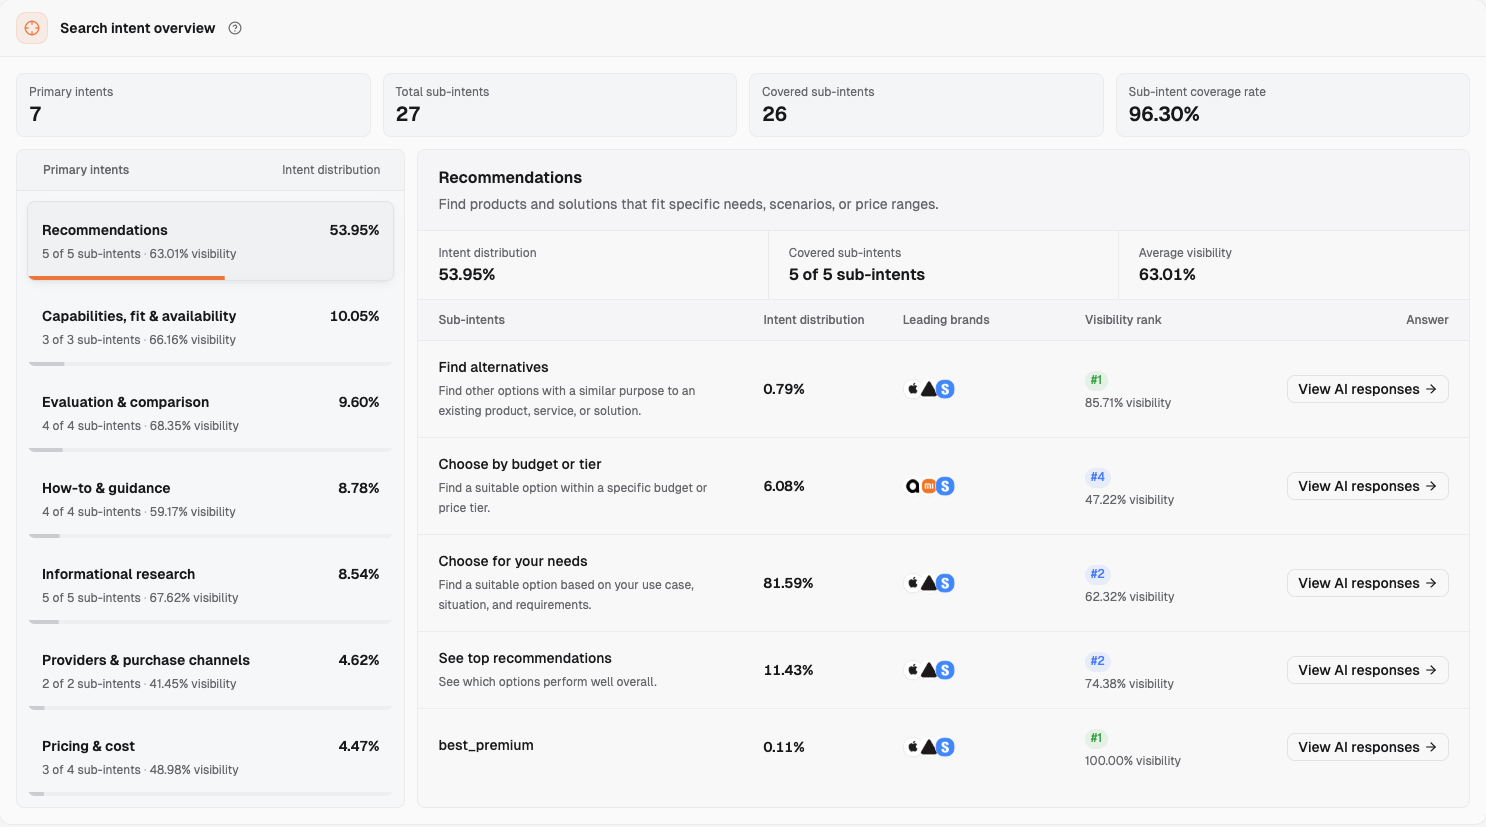
In Search intents, the Recommendations row for Choose by budget or tier shows a Visibility rank of #4, 47.22% visibility, and Amazfit, Xiaomi, and Samsung as the Leading brands. Click View AI responses on that row to open the collected answers for this sub-intent.
Neither ranking tells you the recommendation order in a specific answer. To inspect one answer, click View AI responses, open Evidence preview, and then open Source answer. To check the sources behind the reasons, switch to Related citation analysis.
Record these three layers separately: the market-wide brand visibility ranking, the Visibility rank within a sub-intent, and the brand order a person reads from a Source answer. This prevents "Apple ranks first across the market" from becoming "Apple ranks first for every budget question," and prevents a sub-intent rank of #4 from being treated as fourth place in one answer.
1.3 Fix the Same Sub-Intent, Platform, and Region, Then Review Multiple Answers
The Evidence preview panel does not show the original prompt or the collection time. You therefore cannot compare the wording of the questions word for word from this entry point, and prompts under Choose by budget or tier may use different wording. The smallest fixed scope available for this case is the same sub-intent, platform, and region.
Among the 108 pages of answers for Choose by budget or tier, three are from Google AI Mode in Germany, on pages 2, 7, and 53:
| Page | Are Apple and competitors both candidates? | Manual reading |
|---|---|---|
| Page 2 | Yes | Pixel Watch 3, Samsung Galaxy Watch 8, and Apple Watch SE 3 appear in that order |
| Page 7 | Yes | Pixel and Apple are in separate Android and iPhone groups, with no ranking between the groups |
| Page 53 | No | Apple is only a price reference, not a candidate |
Only pages 2 and 7 are comparable, and only page 2 actually places competitors before Apple. These records are currently only a case lead; they do not show that the brand consistently ranks behind competitors.
The SparkToro study on the consistency of AI recommendations, conducted with Gumshoe, also documented changes in recommendation lists and order. Individual answers are useful for investigating reasons. Multiple comparable answers are needed to judge whether the issue persists.
If your team maintains its own questions in Monitoring settings -> Monitored prompts, the Prompt, Platforms, Regions, and Answers columns can fix the question and observation scope.
2. Compare the Competitor and Your Brand Side by Side: What Reasons Did AI Give Each One?
2.1 Build One Comparison Row From the Same Answer
Page 2 from Germany's Google AI Mode discusses smartwatches under EUR 300. It opens by naming the Pixel Watch 3 the "best all-rounder," while the Apple Watch SE 3 appears third in both the comparison table and the product-by-product discussion. Put the original wording, value props, and sources for both brands in one row. The gap becomes clearer than simply saying "the brand ranks third."
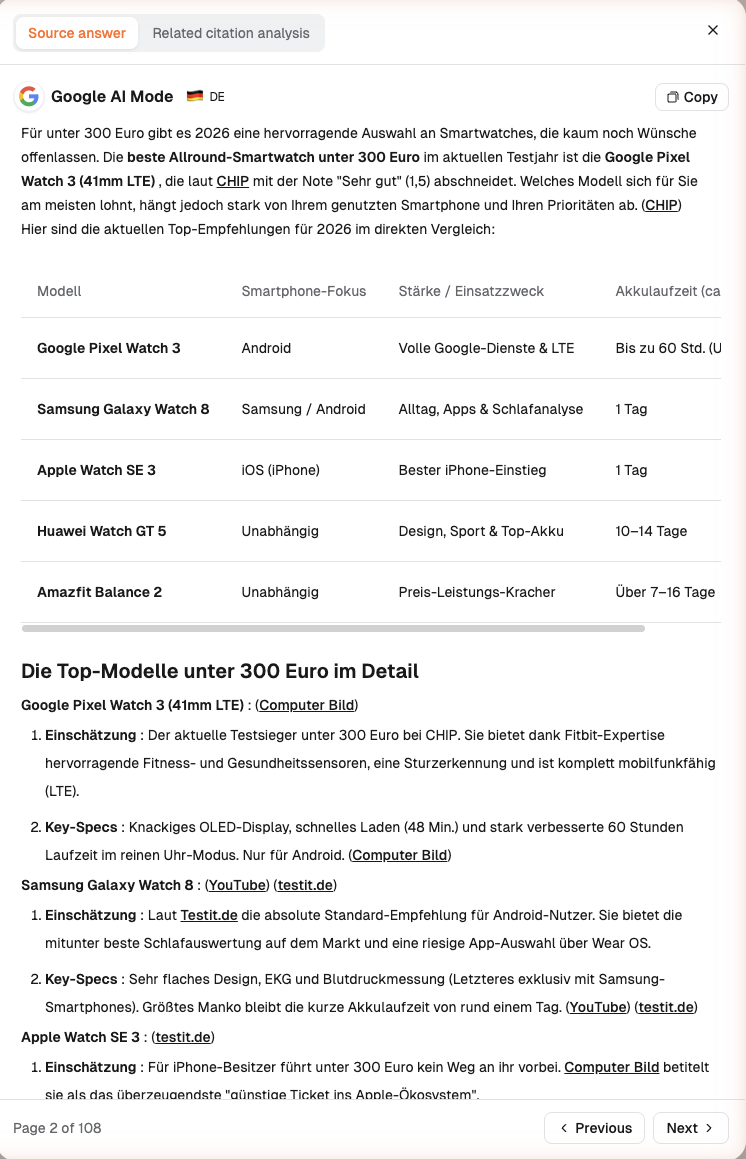
The Source answer from Google AI Mode in Germany (DE), page 2 of 108: the opening calls the Pixel Watch 3 the "best all-rounder" under EUR 300 and cites CHIP's rating. In the comparison table, the Apple Watch SE 3 appears in the third row, labeled iOS (iPhone) and "Bester iPhone-Einstieg."
| Scope | Competitor position and original reason | Brand position and original reason | Related value prop | Visible sources | Product fact check |
|---|---|---|---|---|---|
| Choose by budget or tier; Google AI Mode; DE; page 2 of 108 | Pixel Watch 3, #1: “Die beste Allround-Smartwatch unter 300 Euro im aktuellen Testjahr ist die Google Pixel Watch 3 (41mm LTE), die laut CHIP mit der Note "Sehr gut" (1,5) abschneidet.” (The best all-round smartwatch under EUR 300 in the current test year is the Pixel Watch 3, which CHIP rated "Very good (1.5).") | Apple Watch SE 3, #3: “Für iPhone-Besitzer führt unter 300 Euro kein Weg an ihr vorbei. Computer Bild betitelt sie als das überzeugendste "günstige Ticket ins Apple-Ökosystem".” (For iPhone owners, there is no getting around it under EUR 300.) | Pixel: budget all-round performance and review score; Apple: entry point for iPhone users and ecosystem integration | The answer has 9 third-party sources and no apple.com source, including the CHIP budget smartwatch review, the Computer Bild smartwatch ranking, and the testit smartwatch page | Apple's website says the SE 3 requires an iPhone 11 or later. "EKG App nicht verfügbar" and "Blutsauerstoff App nicht verfügbar" match the answer's iPhone requirement and lack of ECG and blood oxygen measurement |
Keep the original wording in the table before categorizing each reason. Do not turn "best all-rounder" into your team's own marketing claim, and do not assume that any third-party link means the evidence is sufficient. Open every URL and confirm which product, market, and claim it supports.
2.2 Record the Answer in the Platform, and Have the Brand Confirm Product Facts
The platform can provide the platform, region, answer text, Citations · N sources, and individual source pages. The Brand × value prop share heatmap under Brand value props also shows which value props AI mentions together with each brand.
Product facts must be checked against the brand's current materials. For example, Apple's German Apple Watch SE 3 page lists an Always-On Retina Display, says the ECG and blood oxygen apps are unavailable, and states that an iPhone 11 or later is required. It can verify the compatibility and feature boundaries described in the answer.
The heatmap counts associated mentions only. Co-occurrence among competitor pages, sources, and value props can help the team form a line of inquiry, but the diagnosis still has to return to the Source answer, the specific sources, and current product facts.
3. How to Separate the Three Causes: Rule Out Poor Product Fit First, Then Check Value Props and Evidence
3.1 Poor Product Fit: The Brand Does Not Meet a Hard Requirement
Start with the hard requirements in the question. For Android users, Apple's website already states that the SE 3 requires an iPhone 11 or later. Pixel's "Nur für Android" (For Android only) and Apple's iPhone requirement target different users. If this were your brand, you should mark budget smartwatch questions for Android users as not worth competing for, rather than asking the content team to rewrite compatibility information.
Two Gemini records from Austria offer a more direct example. Both appear under Choose by budget or tier, on pages 46 and 51. Judging from the answer content, the questions focus on "low price + ECG," and both answers put Apple in fourth place. Page 51 says:
“Wichtig: Die günstigere Apple Watch SE hat keine EKG-Funktion! Du musst zu den normalen Series-Modellen greifen.” (Important: The cheaper Apple Watch SE does not have an ECG feature. You need to choose a standard Series model.)
Apple's SE 3 page says "EKG App nicht verfügbar" (ECG app unavailable). Neither answer has a Citations section, so record them as "no visible citations." The hard requirement can be checked directly against the official product fact: the current budget model does not have ECG, and a content update cannot change that product condition.
3.2 Unclear Value Props: The Answer, Value-Prop Association, and Your Own Page Must Point to the Same Gap
There are three checks for an unclear value prop. First, see whether AI's reason for the brand is vague or off-topic. Next, check the association with the target value prop in the heatmap. Finally, read your own page to see whether it omits the product, conditions, limitations, or intended user. Only add information to the page when all three checks point to the same missing information.
This review did not find a real example of that pattern. In the heatmap, Apple has 358 associated mentions for Seamless Ecosystem Integration and ranks first for that value prop. Amazfit leads Price Affordability, with 128 mentions versus Apple's 60. This matches the wording on page 2, which presents Apple as an entry point to the iPhone ecosystem. These numbers count mentions in AI answers; they are not product performance scores.
Page 7 instead shows why all three sources of evidence must be checked. It says of the Apple Watch SE 3:
“Funktioniert ausschließlich mit iPhones und hat keine Always-On-Display-Option in der Basisvariante. (Computer Bild)” (Works only with iPhones and has no always-on display option in the base model.)
Apple's website lists an "Always-On Retina Display," while the Computer Bild page cited by the answer also says "Erstmals gibt es ein Always-on-Display." The three sources do not point to a gap on the product page; the problem is in the answer itself. The team should add it to a factual correction log and follow the process for correcting inaccurate AI brand information to check the source and later answers, rather than creating another page for information that already exists.
3.3 Weak Evidence: The Value Prop Appears, but the Current Model Lacks Comparable External Support
Page 2 names the Pixel Watch 3 the "best all-rounder" and cites CHIP's review score. When the budget smartwatch review page was read on 2026-09-28, it called the Pixel Watch 3 LTE 41mm the "Beste Smartwatch unter 300 Euro," with a Testurteil of "Sehr gut (1,5)." The only Apple product in the same comparison table was the Apple Watch SE (2022), rated "Gut," and "SE 3" did not appear anywhere on the page.
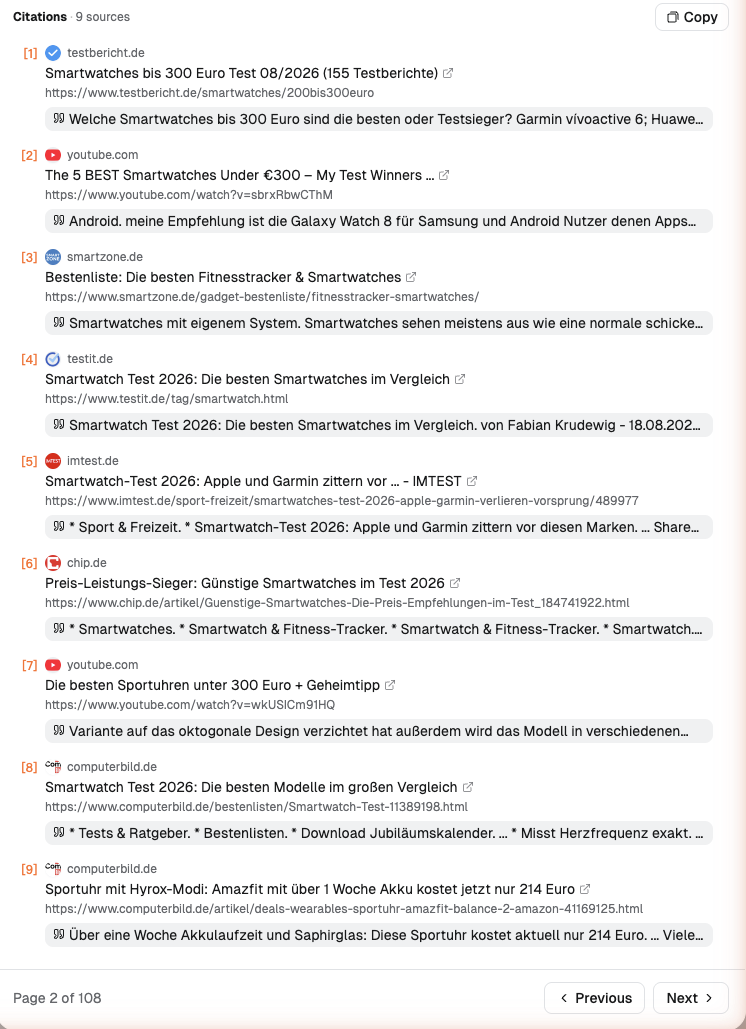
The same answer has Citations · 9 sources, all of them third-party pages. Source [6] is chip.de's budget smartwatch review, and source [8] is computerbild.de's smartwatch ranking.
This is a signal of an evidence gap: the budget review cited by the answer covers the Pixel Watch 3 recommended in the answer, but not Apple's current budget model. This observation cannot prove that the difference in page coverage caused the order in the answer; because the page was read on 2026-09-28, it also cannot reconstruct the version available when the answer was collected.
A weak-evidence diagnosis must specify which claim lacks what kind of proof. Here, the question is whether the current budget model appears in an independent review for the same price tier, and whether that review covers compatibility, feature boundaries, and real usage conditions. The goal is not a vague increase in third-party mentions.
3.4 Use One Table to Identify the Primary Cause
| What you see | What to check next | Current conclusion | Action |
|---|---|---|---|
| The question requires Android compatibility or a budget model with ECG, and the product does not meet that requirement | Current model, region, compatibility, and feature conditions | Poor product fit | Stop competing for the question |
| AI's reason is vague, the target value-prop association is weak, and your own page also lacks the same information | Source answer, Brand value props, and the relevant product page | Unclear value prop | Add specific information to the page |
| AI states the value prop, the competitor has an independent review under the same conditions, and the brand's current model lacks comparable coverage | The specific URL behind the reason, model, and page date | Signal of an evidence gap | Add external proof that matches the claim |
| The answer conflicts with the official page and its own cited source | Official facts and the wording on the cited page | Factual error | Add it to the factual correction log |
4. Choose the Action Based on the Cause: Add Information, Add Proof, or Stop Competing for the Question
4.1 Confirm Fit First, Then Address Information and Evidence
This order determines who should own the task. If the product does not meet a hard requirement, the growth team should stop competing for that question. If the product fits but the page is unclear, product marketing and content teams should add the facts. If the page is already clear but external materials do not cover the current model or key claim, PR, customer marketing, or review-partnership owners can prepare evidence materials.
Checking fit first also avoids two kinds of wasted work: writing content for a capability the product does not have, and asking external authors to validate a product before the first-party facts are clear.
4.2 When the Value Prop Is Unclear, Specify the Page and the Sentence
Adding information does not mean "write another article." Capabilities, versions, and prerequisites belong on product or specification pages. Common eligibility conditions and limitations belong in an FAQ. Update a comparison page when users need to choose among products under the same conditions.
An actionable task should read: "Update the product page for the target region. In the compatibility section, add the current model, required device, operating system version, supported capabilities, and limitations, with a current source beside each fact." The task should also include the page URL, placement, product approver, publication date, and review date.
Google's guide to content for generative search emphasizes useful, reliable, people-first information. Its guidance on AI features and websites explains how AI features find supporting links. The Microsoft Advertising guide to AI search content recommends organizing facts with clear headings, direct answers, lists, and comparison tables. Format supports product facts; it does not replace them.
In this case, Apple's website already states the iPhone requirement, Always-On Display, and the ECG and blood oxygen feature boundaries. Those details are not missing information that needs to be added.
4.3 When Evidence Is Weak, Let Independent Sources Review the Actual Product
If this were your brand, first check whether the current budget model appears in the budget reviews cited by AI. If a review still covers an older model, you can provide the independent reviewer with a current sample, specification materials, compatibility conditions, and a repeatable test method. The reviewer should independently decide whether to test it, how to compare it, and whether to include it.
Performance claims need a test method and environment. Compatibility needs device and system conditions. Price claims need a region, date, and list of included items. The purpose of providing these materials is to let a third party verify the current product, not to buy a citation placement.
4.4 When the Product Is a Poor Fit, Explicitly Stop Competing
For budget smartwatch questions aimed at Android users, if this were your brand, you should mark them as not worth competing for. The website already states the SE 3's iPhone requirement, so no additional information is needed for this question. The team can redirect resources to iPhone users, ecosystem integration, or other needs the product genuinely meets.
Likewise, when a question requires both "low price + ECG," start with current product facts. Reassess whether to compete for this type of question only after the product conditions change.
4.5 Keep One Primary Action for Each Question
| Fixed scope | Primary cause | Current decision | Deliverable | Owner | Review condition |
|---|---|---|---|---|---|
| Choose by budget or tier; Android users; target region | Poor product fit | Stop competing | Record the iPhone requirement and official source | Product marketing | Reassess when compatibility changes |
| Choose by budget or tier; budget all-rounder; target region | Signal of an evidence gap | Add proof | Current model, specifications, test conditions, and available review sample | PR or review-partnership owner | Observe answers again after the independent page is updated |
| Any fitting question where all three checks point to the same page gap | Unclear value prop | Add information | Specified URL, exact sentence, placement, and source | Content and product owners | Review under the original scope after publication |
| Answer conflicts with official material | Factual error | Create a correction log entry | Incorrect wording, source, official evidence, and discovery date | Brand or product marketing | Check whether later comparable answers are accurate |
5. Review: What to Hold Constant, and What You Still Cannot Prove
For review, keep the same sub-intent, platform, and region. Because Evidence preview does not show the original prompt or collection time, your log should retain the page number, review date, platform, region, brand order, grouping method, original reasons, and source URLs. When your team monitors its own questions through Monitored prompts, use Prompt, Platforms, Regions, and Answers to fix the exact question.
After a page or external source changes, record the date and details of the change separately. In the next observation round, continue updating the comparison table row by row: whether the brand and competitor both appear as candidates, whether the answer uses groups, how each reason changes, whether the cited pages change, and whether product facts are described accurately.
This review can show what happened in answers within the fixed scope. Causal claims require additional design, so record a one-time change in order only as a new observation. For a complete logging method, see how to verify changes in AI recommendations after updating your website or external evidence.
6. Conclusion
When your brand appears in a recommendation list behind competitors, do not turn the task into "improve the ranking." First check whether the answer uses groups. Then fix the same sub-intent, platform, and region, and compare the competitor's reason, your brand's reason, cited pages, and current product facts row by row.
If the product does not meet a hard requirement, stop competing for the question. If the product fits but both AI's description and your own page lack the same information, update the page. If the value prop already appears, competitors have independent evidence under the same conditions, and the brand's current model lacks comparable coverage, add proof. For each question, keep one primary action, one owner, and a reviewable set of evidence.
7. FAQ
If AI Lists My Brand Behind a Competitor, Does That Mean the Competitor Has a Better Product?
First check whether the brand and competitor are in the same candidate group. Then compare the price, compatibility, features, and intended users behind each reason. The answer order shows how that answer organized its candidates. Product performance still has to be checked against current specifications, tests, and usage conditions.
If an Answer Groups Brands by Mobile System or Price Tier, Is Appearing Later a Problem?
The order between groups is not a ranking. Record the grouping condition, then check whether there is a clear order within the same group. Germany's page 7 discusses Android before iPhone, but the two brands serve different systems, so record it as "grouped by system."
Why Can a Brand Rank First Across the Market but Fourth in a Budget Sub-Intent?
The two results cover different sets of answers. AI visibility leaderboard aggregates collected answers across the whole market, while the Visibility rank for Choose by budget or tier covers only that sub-intent. The order within one answer still has to be read manually in Source answer.
The Product Fits, but AI Gives a Vague Reason. Which Page Should We Update First?
First confirm whether the answer, the brand's value-prop association, and your own page all lack the same information. Put capabilities and conditions on the product or specification page, common limitations in the FAQ, and same-condition selection reasons on a comparison page. Define the task by URL, sentence, placement, owner, and factual source.
If We Update a Page or External Evidence and Rank Ahead Next Time, Does That Count as Improvement?
Record it as a new observation, then continue reviewing multiple answers within the same scope. Track candidate order, grouping, reasons, citations, and factual accuracy separately so the record does not reduce everything to a single change in position.
8. References
- SparkToro: Study on the Consistency of AI Brand Recommendations
- Google Search Central: AI Features and Your Website
- Google Search Central: Top Ways to Ensure Your Content Performs Well in Google's AI Experiences
- Microsoft Advertising: Optimizing Your Content for Inclusion in AI Search Answers
- Apple Germany: Apple Watch SE 3
About the Author
Updated by
Dageno
Dageno is the research and insights team at Dageno AI, publishing industry reports and expert analysis on AI Search Visibility, Generative Engine Optimization (GEO), and AI-powered search discovery.